Davies-Bouldin, Calinski-Harabasz and silhouette: three clustering metrics SEOs should not confuse
Internal clustering metrics reward different geometric properties. Learn how silhouette, Davies-Bouldin and Calinski-Harabasz differ and why none can validate an SEO page decision.

Farky Rafiq
Founder of ClusterIQ

When you are staring at a spreadsheet of three thousand keywords exported from Ahrefs or Search Console, the first instinct is to group them so you can actually do something with them. Modern clustering libraries make this grouping process remarkably fast, but they often spit out a series of technical scores that can feel like a distraction from the actual task of building a content plan. The challenge isn't getting the numbers; it is knowing which ones actually signal a better result for your SEO strategy.
Metrics like Silhouette, Davies-Bouldin and Calinski-Harabasz are internal measures. They look at the mathematical "shape" of your keyword groups without needing a pre-defined map of what the topics should be. While they are brilliant for testing different settings, they should never be treated as a final verdict on whether your SEO clusters are correct.
Silhouette measures cohesion relative to separation
The Silhouette score looks at how well an individual keyword fits into its assigned group compared to the next best alternative. It produces a value between -1 and 1, where higher numbers are generally preferred.
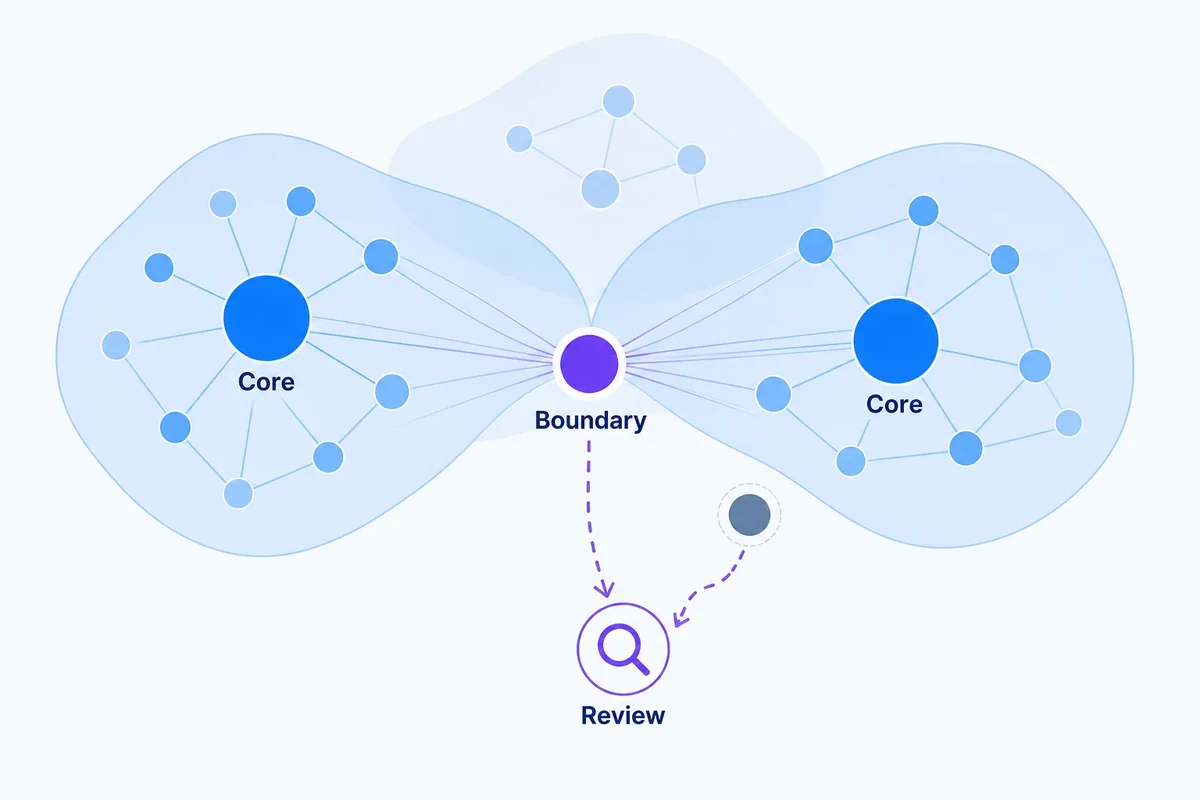
In practice, this is a fantastic way to spot "boundary problems" where a keyword could arguably sit in two different buckets. However, the score is heavily influenced by how you have represented your data and the specific way you measure the distance between words.
Davies-Bouldin rewards compact, separated clusters
The Davies-Bouldin index evaluates the ratio of within-cluster scatter to the distance between the clusters themselves. In this case, a lower score is actually better.
If you have a low score, it means your keyword groups are tight and well-defined, with plenty of "clear air" between them. This is helpful when you want distinct, centroid-style groupings, but it can be misleading if your topics are naturally messy or vary significantly in density.
Calinski-Harabasz uses variance ratios
The Calinski-Harabasz score, sometimes called the Variance Ratio Criterion, compares the dispersion between different clusters against the dispersion within each cluster. Higher values are usually seen as better. It is particularly effective when you are trying to decide on the ideal number of groups (the value of k) for your dataset.
The direction of “better” differs
- Silhouette: higher is better.
- Davies-Bouldin: lower is better.
- Calinski-Harabasz: higher is better.
A well-designed ClusterIQ dashboard should make these directions clear, rather than just dropping three confusing numbers onto your screen without context.
The metrics can disagree
Because these metrics reward different geometric traits, they often conflict. You might tweak your settings and see the Silhouette score go up while Davies-Bouldin gets worse. You might even see a high Calinski-Harabasz score simply because the model has merged important subtopics into giant, distant groups.
This disagreement isn't a failure of the model. It is a signal that your keyword data has complex structural properties that a single number cannot capture.
They are weak as cross-representation comparisons
If you run one test using traditional TF-IDF vectors and another using modern semantic embeddings, you cannot compare their scores directly. The metrics are calculated within different mathematical "spaces". A higher score in one method does not guarantee that the resulting content plan will be more useful for your site.
These internal metrics are most reliable when you are comparing different settings within the same data representation.
Worked example: ecommerce attributes
Consider a list of keywords for shower products. One model might group everything into broad categories like "Electric Showers" and "Mixer Showers". This creates very tight, compact clusters that score well mathematically. However, another model might preserve nuances like colour, flow rate and mounting type, creating more complex boundaries and slightly lower scores.
If your site architecture relies on those specific attributes for filtering, the "messier" model is actually the superior one. This is why ClusterIQ combines these metrics with entity-aware evidence and a final review by a human expert.
Density-based clustering needs different diagnostics
Algorithms like HDBSCAN are designed to find clusters of varying shapes and to filter out "noise". Metrics that reward perfect circles or compact spheres will often penalise these models, even when the results are highly logical.
When using density-based models, you should look at noise rates, how confident the model is in each keyword's membership and how stable the clusters remain when parameters change.
Graph communities need graph metrics
If you are using Louvain or Leiden algorithms to find communities in a keyword graph, metrics like modularity are more relevant than centroid-based scores. Even so, no graph metric can tell you if a cluster actually matches a user's search intent.
Your evaluation should always match the method you chose, rather than forcing a generic score onto every single model.
Use a dashboard of evidence, not a composite mystery number
It is tempting to smash all these scores into one "Quality Grade". The problem is that the weighting is arbitrary and hides the reasons why a specific run was better or worse.
A more practical approach in ClusterIQ is to display geometry, stability and human benchmarks separately. This allows the SEO to see exactly what changed in the data structure.
How to compare configurations properly
- Keep your dataset and data representation exactly the same.
- Change only one meaningful setting at a time.
- Check the relevant internal metrics.
- Compare the results against your own human benchmark.
- Look closely at the keywords on the boundaries of clusters.
- Determine if the changes would actually alter your URL or page-level decisions.
Do not optimise away ambiguity
A model can often "improve" its scores by ignoring difficult keywords or forcing everything into broad, vague groups. This makes the charts look cleaner, but it hides the very queries that usually require the most attention from a strategist.
Ambiguity is a natural part of search data, not a bug that needs to be polished away.
Practitioner principle: internal metrics are evidence about geometry. SEO quality is a separate judgement about whether the structure helps users and site decisions.
ClusterIQ Conclusion
While Silhouette, Davies-Bouldin and Calinski-Harabasz offer vital diagnostic clues, they are not a substitute for SEO expertise. They should never be blended into a single, unquestioned score.
Use the metric that suits your specific clustering method, ensure you are comparing like-for-like runs and always validate the output against real-world business requirements.
Compare metric movement with decision movement
When a score moves, ask yourself if the SEO output actually improved. Did those high-value keywords move into more logical groups? Did clusters with mixed intent get separated? Or did the model just make the groups look more compact on a graph?
ClusterIQ shows these metric shifts alongside membership changes and benchmark results. This stops teams from chasing a better Davies-Bouldin score when the actual page-level strategy remains flawed.
The real test isn't whether the math looks pretty. It is whether the new configuration helps you make better decisions faster, without introducing new errors into your content plan.
Sources and further reading
Farky Rafiq
Founder of ClusterIQ
I've worked in digital marketing since 2005 and founded Liquid Silver in 2011. These articles are where I share the methods, experiments and practical SEO thinking behind ClusterIQ.
Put the idea into practice with your own keyword data
ClusterIQ helps turn raw SEO exports into clean, structured working datasets you can inspect, refine, report on and take into the next stage of your workflow.
Keep reading
Soft clustering and confidence scores: handling ambiguous keywords honestly

Adding new keywords to existing clusters without rebuilding everything